Modern businesses depend on reliable IT infrastructure to manage daily operations, support customers and maintain access to essential digital services. As organisations expand their online activities, the demand placed on servers, networks and cloud environments can increase significantly. Website traffic, database requests, business applications and internal communication systems all contribute to infrastructure workloads. When these demands rise unexpectedly, servers may experience performance issues, slower response times or temporary service interruptions.
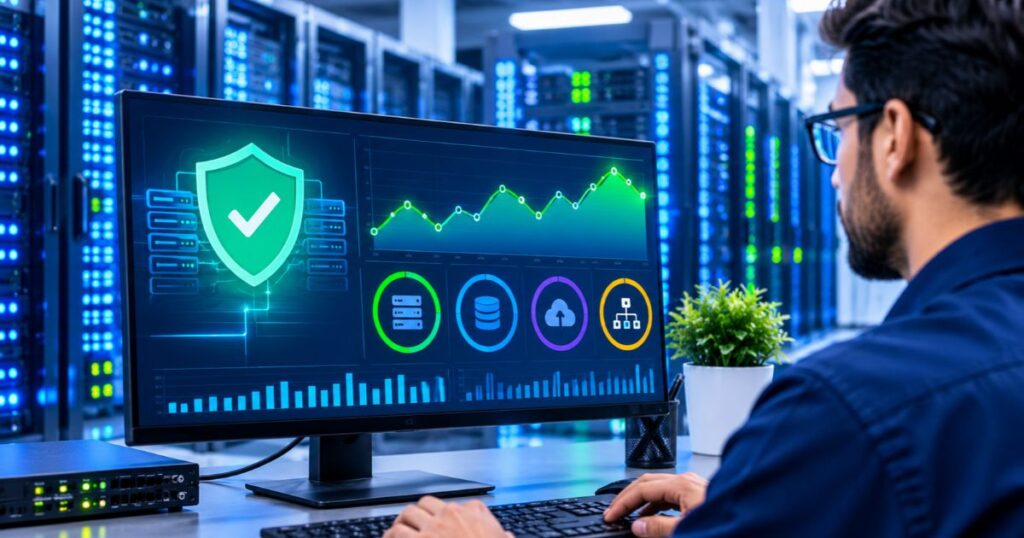
Continuous infrastructure monitoring helps businesses understand how their IT systems behave under different workload conditions. By tracking server performance, network activity, resource utilisation and system availability, IT teams can identify potential problems before they develop into major disruptions. This approach is particularly important for organisations that rely on uninterrupted access to digital platforms and business applications.
Understanding Continuous Infrastructure Monitoring
Continuous infrastructure monitoring is the ongoing process of observing and analysing the performance, availability and health of an organisation’s IT environment. It involves collecting operational data from servers, network devices, storage systems, databases and cloud-based resources. This information helps IT administrators understand whether infrastructure components are operating within their expected performance limits.
Unlike occasional system checks, continuous monitoring provides ongoing visibility into infrastructure conditions. IT teams can observe changes in resource consumption, identify unusual activity and investigate performance variations as they occur. For businesses using multiple servers or distributed IT environments, this visibility makes it easier to understand how different components interact and influence overall system performance.
Monitoring also helps establish a performance baseline. A baseline represents the normal operating behaviour of an IT system under typical conditions. When current performance differs significantly from this baseline, administrators can investigate the reason behind the change. For example, an unexpected increase in CPU utilisation or network traffic may indicate higher workloads, application inefficiencies or unusual system activity.
Why Increased Network Demand Can Affect Server Availability
Network demand can increase for several reasons, including seasonal website traffic, marketing campaigns, business expansion, software updates and increased customer activity. When more users access applications or online services simultaneously, servers must process additional requests and exchange larger amounts of data.
If infrastructure resources are not sufficient to handle these workloads, performance can deteriorate. Servers may take longer to respond, applications can become less responsive and database operations may experience delays. In more severe situations, systems can become unavailable because they cannot process incoming requests efficiently.
Network congestion is another factor that can affect availability. When network devices handle more traffic than their available capacity allows, data transmission may experience delays or packet loss. This can affect communication between servers, applications and end users.
Continuous monitoring helps administrators understand these conditions by providing information about traffic patterns, bandwidth consumption, response times and resource utilisation. Instead of waiting for users to report problems, IT teams can investigate unusual performance changes and take appropriate action.
How Continuous Monitoring Helps Prevent Server Downtime
One of the main advantages of continuous infrastructure monitoring is its ability to identify performance issues at an early stage. Server downtime does not always happen suddenly. In many cases, system failures are preceded by warning signs such as increasing memory consumption, unusual processor activity, insufficient storage space or repeated application errors.
By observing these indicators, administrators can identify developing problems and investigate them before they affect service availability. For example, a server experiencing consistently high memory usage may eventually become unresponsive if applications continue consuming additional resources. Monitoring makes it possible to recognise this pattern and investigate memory leaks, unnecessary processes or resource allocation problems.
Automated alerts provide another layer of protection. Administrators can configure notifications when specific performance measurements exceed predefined thresholds. These alerts help technical teams respond to unusual conditions without manually checking every infrastructure component throughout the day.
For organisations investing in server monitoring Miami solutions, continuous visibility can support faster identification of infrastructure issues and more informed decisions about maintaining system availability. The objective is not simply to collect performance data but to use that information to reduce the likelihood and impact of service interruptions.
Monitoring CPU, Memory and Storage Utilisation
Server resources directly influence the ability of infrastructure to handle incoming workloads. CPU utilisation indicates how much processing capacity is being used, while memory utilisation shows how much available RAM is occupied by applications and operating system processes.
When CPU usage remains consistently high, applications may experience slower processing times. This can happen when servers handle excessive requests, inefficient software operations or resource-intensive background tasks. Monitoring CPU activity helps administrators determine whether increased demand is responsible for performance changes.
Memory monitoring is equally important. Applications require sufficient memory to process information and maintain their operations. When available memory becomes limited, systems may rely more heavily on disk-based virtual memory, which can reduce performance. Continuous observation helps identify unusual memory consumption and recurring resource shortages.
Storage monitoring focuses on disk capacity, read and write activity, and storage response times. A server with insufficient available storage may encounter problems when saving files, creating temporary data or updating databases. Monitoring storage performance helps administrators identify capacity limitations before they affect critical applications.
Together, these measurements provide a clearer understanding of server health and help businesses determine whether their infrastructure can support increasing workloads.
The Importance of Network Traffic and Bandwidth Monitoring
Server performance depends on more than processing power and memory. Network connectivity also plays a significant role in maintaining service availability. Even when servers have sufficient resources, network congestion can prevent applications from communicating efficiently with users and other infrastructure components.
Bandwidth monitoring helps IT teams understand how much network capacity is being consumed over time. It can reveal periods of unusually high traffic, recurring congestion and differences between expected and actual usage patterns.
Network latency is another important measurement. It represents the time required for data to travel between two points. Higher latency can make applications feel slower, particularly when they depend on frequent communication between servers, databases and external services.
Packet loss should also be monitored because missing data packets may require retransmission, increasing communication delays. In some situations, persistent packet loss can affect application reliability and user experience.
By combining bandwidth, latency and packet-loss measurements, administrators can identify whether network conditions are contributing to performance problems. This information is useful when evaluating network capacity, reviewing traffic distribution and planning infrastructure improvements.
Using Automated Alerts to Improve IT Response Times
Manual infrastructure checks can become difficult as organisations add more servers, applications and network devices. Automated monitoring alerts help address this challenge by notifying administrators when specific system conditions require attention.
Alerts can be configured for different infrastructure measurements, including high CPU usage, low available memory, storage capacity limits, server unavailability and unusual network traffic. The thresholds should reflect the operating requirements of each system rather than relying on identical settings across every server.
For example, a temporary increase in CPU usage may be normal during scheduled processing activities. However, consistently high utilisation outside expected operating periods may indicate an underlying issue. Well-configured alerts help distinguish between normal workload variations and conditions that require investigation.
Alert prioritisation is also important. Critical infrastructure failures should receive immediate attention, while less urgent performance warnings can be reviewed through routine maintenance processes. This reduces unnecessary notifications and helps IT teams focus on the issues with the greatest potential impact.
An effective alerting process should also include clear escalation procedures. Administrators need to know who is responsible for investigating an alert, how the issue should be documented and when additional technical support is required.
Capacity Planning for Periods of Increased Network Demand
Continuous infrastructure monitoring provides valuable information for long-term capacity planning. Instead of estimating future requirements based on assumptions, organisations can use historical performance data to understand how infrastructure resources are consumed over time.
For example, monitoring records may show that website traffic regularly increases during promotional campaigns or specific business periods. IT teams can use these patterns to estimate the additional processing power, memory, storage and bandwidth required to support future demand.
Capacity planning also helps identify infrastructure components that are approaching their operational limits. A server that consistently operates close to its available capacity may have limited room to accommodate additional users or application requests.
Businesses can respond by optimising applications, upgrading hardware, distributing workloads or adopting scalable cloud resources. The appropriate solution depends on the organisation’s technical requirements, budget and existing infrastructure design.
Through server monitoring Miami strategies, organisations can use performance trends to make more informed infrastructure decisions and prepare for changes in network demand before capacity limitations affect service delivery.
The Role of Load Balancing in Maintaining Server Availability
Load balancing is a technique used to distribute incoming application requests across multiple servers or infrastructure resources. Rather than directing all requests towards a single server, a load balancer distributes workloads according to configured rules and the availability of backend systems.
This approach can improve resource utilisation and reduce the risk of individual servers becoming overloaded. For example, when website traffic increases, requests can be distributed across several application servers to prevent one system from handling the entire workload.
Load balancing can also support availability when one server becomes unhealthy. Depending on the configuration, the load balancer may stop directing new requests towards that server and use other available resources.
However, load balancing does not automatically eliminate every infrastructure risk. The load balancer itself must be monitored, and backend servers need sufficient capacity to handle redistributed workloads. Network connectivity, application dependencies and database performance must also be considered.
Combining load balancing with continuous infrastructure monitoring gives administrators better visibility into how workloads are distributed and whether individual components are experiencing excessive demand.
Monitoring Cloud and Hybrid IT Environments
Many organisations operate infrastructure across on-premises data centres, public cloud platforms and hybrid environments. Although these systems offer flexibility, they can also introduce additional monitoring challenges.
Different infrastructure components may use separate management interfaces, monitoring tools and performance metrics. This can make it difficult for administrators to understand how an issue in one environment affects the rest of the system.
Centralised monitoring helps bring operational information together. It allows IT teams to observe server health, network activity, application performance and resource consumption across different environments.
Cloud monitoring is particularly useful for understanding resource utilisation and identifying unexpected changes in infrastructure demand. Organisations can review virtual machine performance, storage activity, network traffic and application response times to determine whether cloud resources are being used efficiently.
Hybrid environments also require visibility into communication between on-premises infrastructure and cloud services. Network latency, connectivity interruptions and configuration problems can affect applications that depend on resources in multiple locations.
A consistent monitoring strategy helps organisations maintain better control over these interconnected systems while supporting reliable access to business applications.
Using Historical Monitoring Data to Identify Performance Trends
Real-time monitoring helps administrators respond to current problems, while historical data supports long-term infrastructure analysis. Performance records can reveal recurring issues that may not be obvious during individual system checks.
For example, a server may experience increased memory consumption every evening because of scheduled application processes. Similarly, network traffic may rise at predictable times when employees access shared applications or customers visit a business website.
Reviewing historical data helps IT teams distinguish between normal workload patterns and unexpected behaviour. It also makes it easier to evaluate whether infrastructure changes have improved performance.
Trend analysis can support decisions about hardware upgrades, software optimisation, storage expansion and network improvements. It can also help organisations establish more realistic performance thresholds based on actual operating conditions.
Maintaining useful historical records is therefore an important part of infrastructure management. Data should be reviewed regularly, and monitoring systems should retain enough information to support troubleshooting and capacity planning.
Best Practices for Building an Effective Infrastructure Monitoring Strategy
An effective monitoring strategy begins with identifying the infrastructure components that are most important to business operations. Organisations should prioritise critical servers, databases, network devices, applications and services that directly support essential business functions.
Monitoring objectives should then be defined for each component. These may include availability targets, acceptable response times, resource utilisation limits and network performance requirements. Clear objectives help administrators determine which measurements need attention and how monitoring results should be interpreted.
It is also important to configure meaningful alert thresholds. Excessively sensitive alerts can generate unnecessary notifications, while thresholds that are too relaxed may delay the identification of serious problems. Settings should reflect the normal operating behaviour and business importance of each system.
Regular reviews are equally necessary. Monitoring tools provide information, but technical teams must analyse that information and take corrective action. Reviewing recurring alerts, investigating performance trends and documenting incidents can help organisations improve their infrastructure management processes over time.
Finally, monitoring coverage should be updated whenever infrastructure changes. Adding new servers, applications, cloud services or network devices without including them in the monitoring strategy can create visibility gaps and make troubleshooting more difficult.
Conclusion
Continuous infrastructure monitoring plays an important role in maintaining server availability when businesses experience increased network demand. By tracking resource utilisation, network performance, application behaviour and system health, organisations can identify potential issues before they cause significant service interruptions.
Automated alerts, historical performance analysis, capacity planning and load balancing further support infrastructure reliability. These practices allow IT teams to understand changing workloads, respond to technical problems and make informed decisions about future resource requirements.
For businesses operating in demanding digital environments, server monitoring Miami strategies can provide the operational visibility needed to manage infrastructure more effectively. Consistent monitoring, combined with regular maintenance and appropriate capacity planning, helps organisations maintain dependable IT services as their operational requirements grow.
Discover More Articles:
